What is AI Search for Large Catalogs
Why large catalogs are a different problem
The naive assumption is that scale is linear: ten times the products, ten times the resources, same architecture. Reality is less polite, for four compounding reasons.
AI Search Grader by bCloud AI
Grade your ecommerce search in 10 quick questions
31% of ecommerce searches return zero results — and most shoppers who hit a dead end leave for a competitor. How does your store's search stack up?
Answer 10 short questions and get your AI search score, plus a personalized report to fix the gaps. Free, takes about 2 minutes.
No signup needed to take the quiz.
Understanding intent…
Scoring your answers across relevance, AI, experience, and insights.
Your AI search score is ready
Tell us where to send your personalized report. You'll see your score and recommendations right away.
Your score by pillar
Personalized recommendations
Fix the gaps in weeks, not quarters
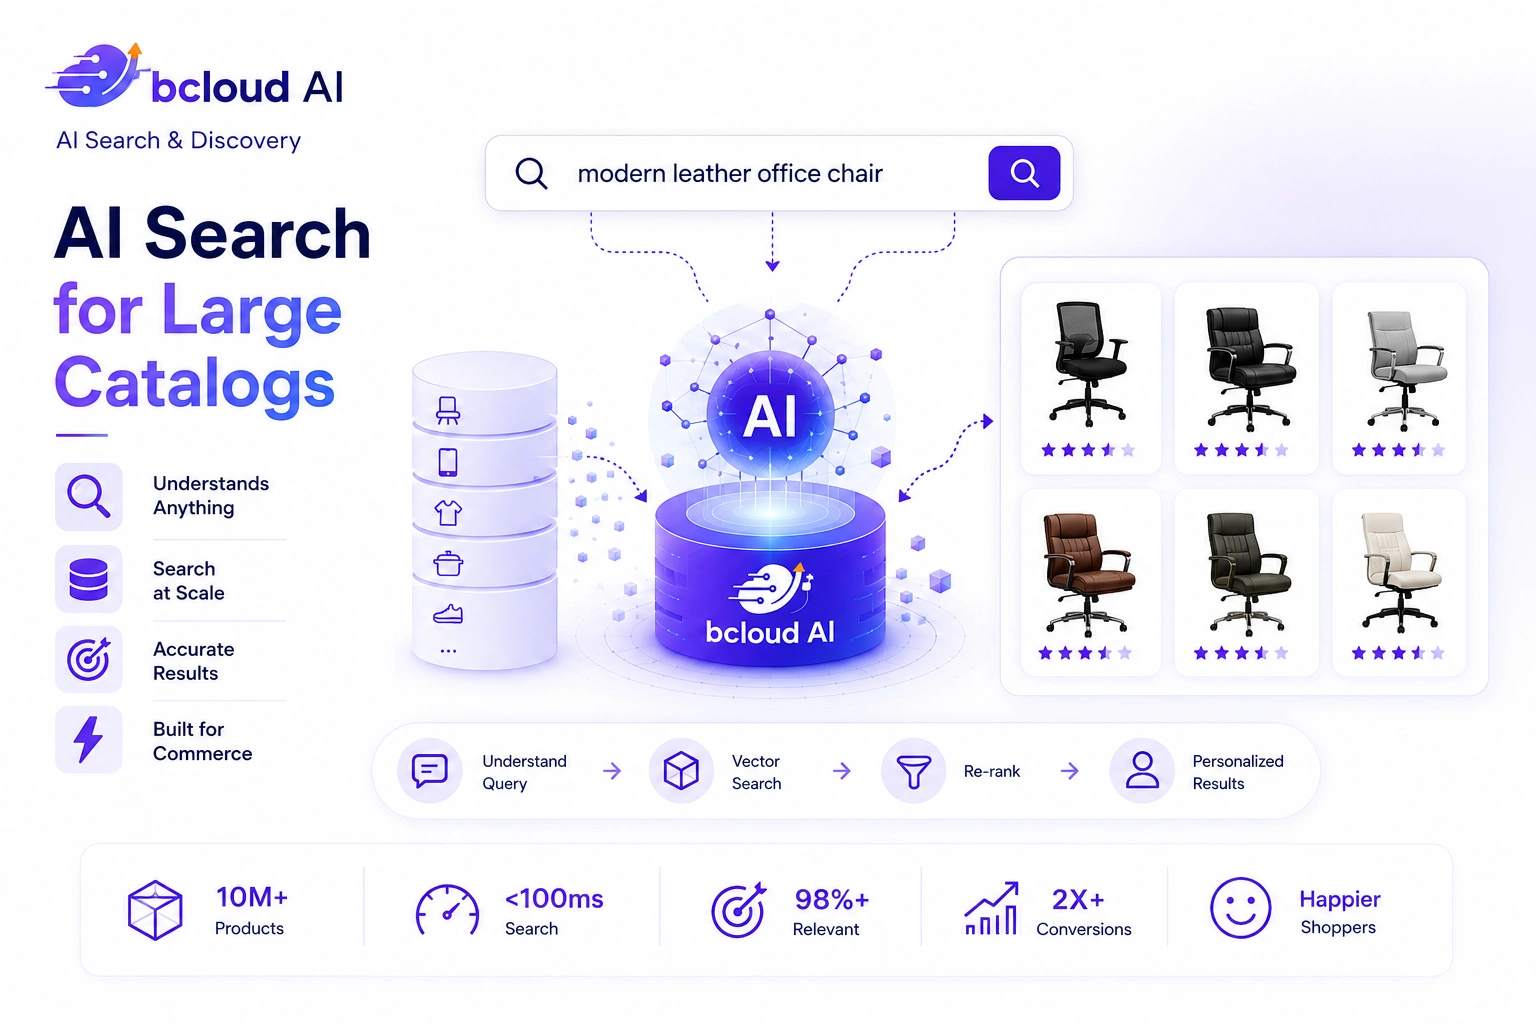
bCloud AI replaces keyword-only search with hybrid AI retrieval — sub-200ms responses, 99.99% uptime, and conversion lifts of up to 40% across 50+ implementations.
Mistake 1: Benchmarking on somebody else’s scale
Vendors demo on tidy indexes. Public benchmarks measure uniform datasets with no filters and no concurrent writes. Neither predicts how a system behaves on your large catalogs.
The fix is unglamorous and decisive: benchmark on your own data, at your projected size, not today’s. Index a representative sample scaled to next year’s catalog, run your real query mix — head terms, long-tail descriptions, SKU lookups — with your real filters applied, under simultaneous indexing load, and read p95/p99 rather than averages. A day of honest benchmarking beats a quarter of vendor claims, and our search relevance metrics guide covers how to score the quality side while you’re at it.
Mistake 2: Ignoring the memory math until the invoice
Full-precision vectors at scale are expensive, and teams discover this at renewal time. The mature answer is quantization: compressing vectors so the index fits in a fraction of the memory. Scalar quantization typically cuts memory around 4× with minimal recall loss; binary quantization goes much further and pairs with a rescoring pass on full-precision vectors to claw accuracy back; product quantization and disk-backed indexes extend the curve for the truly enormous.
The point isn’t which technique — it’s that on large catalogs, quantization strategy is a first-class architectural decision, not an optimization for later. Make it deliberately, measure recall before and after (the silent-degradation trap in our nearest neighbor search guide applies double at scale), and re-check whenever the catalog doubles.
Mistake 3: Treating filters as an afterthought
Here’s the scale-specific trap: on large catalogs, every query is a filtered query — in stock, this region, this price band, this seller. And filtering is precisely where approximate nearest-neighbor systems diverge most.
Pre-filtering can break graph connectivity when constraints eliminate most of the index; post-filtering returns too few results when constraints are tight; only filter-aware traversal holds up when a facet cuts ten million products down to four thousand. The difference between implementations that handle this well and ones that don’t is often the single biggest performance gap you’ll measure. Test with your gnarliest real filters — the multi-facet, low-selectivity ones — because unfiltered numbers on large catalogs are close to fiction.
Mistake 4: One embedding strategy for ten million products
Small stores can embed title-plus-description and move on. Large catalogs need policy. Decide what gets embedded (product vs. variant level, which attributes, whether images join the text), how updates propagate — re-embedding everything on a model change is a genuine migration at this size, as the indexing fundamentals make clear — and how enrichment fills the gaps, because at scale, thin and inconsistent product data is guaranteed somewhere in the assortment. Data enrichment that normalizes attributes and fills missing fields pays off disproportionately on large catalogs, since the engine can only understand what the data expresses. Our embedding models guide covers the model-selection half of this decision, including the dimension-versus-cost trade-off that scale amplifies.
Mistake 5: Pure vector retrieval on a catalog full of part numbers
Large catalogs — especially B2B, electronics, auto, and marketplaces — are dense with exact identifiers: SKUs, MPNs, model codes. Pure semantic retrieval drifts to “close enough” on exactly those queries, and at scale, “close enough” is a support ticket. The production answer is hybrid retrieval: lexical precision and semantic recall fused per query, so “DW745 replacement blade” resolves exactly while “quiet saw for a small workshop” resolves by meaning. The fusion mechanics live in our hybrid search guide, and the underlying speed comes from the same HNSW indexing described in the original paper — tuned, at this size, with recall measured rather than assumed.
Mistake 6: Letting freshness lag hide behind averages
At marketplace velocity, indexing lag is a revenue metric. The failure pattern is always the same: median lag looks fine, while the p99 tail quietly stretches to hours during import storms — precisely when catalogs change most. Track lag as a distribution, isolate indexing load from query serving so writes can’t degrade search latency, and reconcile against the source of truth on a schedule so drift gets counted instead of discovered. The full operating manual is in our real-time indexing guide; on large catalogs, every item in it applies with the volume turned up.
A scale-readiness test you can run this week
Before any vendor conversation, spend a few days measuring where you actually stand — large catalogs punish assumptions, and this audit converts them into numbers.
One nuance for B2B and marketplace operators, where large catalogs are the norm rather than the exception: add seller- and account-scoped filtering to the latency test, and contract-pricing visibility to the freshness test. Both multiply the filtering and indexing loads that already dominate at scale, and both are exactly the constraints generic benchmarks never include.
Run the five measurements and you’ll know which of the six mistakes above you’re already making — usually two, occasionally four — and the fix list writes itself in priority order.
Fixing large catalogs in the right order
The audit usually surfaces several problems at once. Sequence matters.
Some fixes change what every later fix can achieve. Consequently doing them out of order means redoing work. This order holds for most large catalogs.
In short, work upward from correctness to refinement. Re-run the audit after each step, because fixing one constraint often reveals the next. Our real-time indexing guide covers the first step in depth.
What scale-ready AI search looks like
Condensing the above into an evaluation checklist for large catalogs:
That last line is the real fork. Everything above is buildable, and engineering-led marketplaces do build it. For most retailers, the faster path is a platform engineered for this scale: bCloud AI’s AI search engine pairs hybrid keyword-plus-vector retrieval with real-time indexing built for high-SKU catalogs, sub-200ms responses, and catalog-based pricing — so a strong quarter raises revenue, not the search bill. For the wider vendor field, our ecommerce site search software guide and best hybrid search systems roundup compare the options through exactly this scale lens.
From 500K to 5 Million Products: What Changes?
Imagine an online marketplace that starts with 500,000 products. Search is fast, product discovery is simple, and nightly indexing keeps everything up to date. As the business grows to 5 million products, the same search architecture begins to show its limits.
Search queries now compete against millions of documents, product variants multiply the index size, and thousands of inventory updates arrive every hour. Customers searching for the same product suddenly experience slower response times, outdated availability, or less relevant results because the search engine was never designed for this level of scale.
The biggest challenge isn’t simply adding more servers—it’s adapting the search strategy. Large catalogs require intelligent indexing, filter-aware retrieval, hybrid search, and infrastructure that can process continuous catalog changes without affecting search performance.
Businesses that prepare for this transition early can continue delivering fast and relevant search experiences as their catalogs expand. Those that delay often spend significant time rebuilding their search infrastructure after performance issues begin affecting customers.
In large-scale ecommerce, the question is no longer “Can the search engine find the product?” It’s “Can it find the right product instantly—even as the catalog grows every day?” That distinction separates search systems that scale successfully from those that become operational bottlenecks.
Frequently asked questions
Why is AI search harder for large catalogs?
Because scale changes which problems dominate: vector index memory becomes the binding constraint, variants multiply document counts, most items lack behavioral data so ranking must work on the long tail, and constant price and stock changes make batch indexing a correctness problem.
How much memory does vector search need at scale?
Roughly 4KB per product at 1,024 dimensions in full precision — about 40GB of raw vectors at ten million items, before index structures. Quantization typically cuts this several-fold with modest recall loss, which is why compression strategy is a first-class decision on large catalogs.
Should I embed products or variants?
It’s a policy decision with real consequences. Product-level embedding keeps the index smaller and relevance cleaner, with variants resolved by filtering; variant-level embedding helps when variants differ meaningfully in how shoppers describe them. Decide deliberately and test both on your data.
Do large catalogs need hybrid search?
Almost always. Big assortments are dense with exact identifiers where pure semantic retrieval drifts, while descriptive long-tail queries need meaning-based matching. Hybrid retrieval fuses both, which is why it’s the production default at scale.
How do I evaluate search vendors for a large catalog?
Benchmark on your own data at projected scale: real query mix, real filters, concurrent indexing load, p95/p99 latency, recall measured against ground truth, and pricing modeled at three times current volume. Unfiltered demos on small indexes predict nothing.
What breaks first when a catalog grows past a million SKUs?
Usually three things in order: filtered-query latency (as facets fight the vector index), memory cost (as full-precision vectors outgrow the budget), and freshness (as batch reindexing can’t keep pace with catalog velocity). All three are solvable, but only by architecture, not tuning.
Search built for the size you’re becoming.
bCloud AI combines hybrid retrieval and real-time indexing engineered for high-SKU catalogs — sub-200ms at millions of products, priced on your catalog, not your success.