AI Search for Media: Archives, Video, and the Discovery Problem
Why media search is its own problem
01
Archives are deep and mostly dark.
A publisher with twenty years of output has hundreds of thousands or millions of pieces. Most of it never surfaces again, which means the majority of your media content library is effectively invisible — an asset you paid to create and can't retrieve.
02
Recency and relevance pull against each other.
For breaking news, the newest piece wins. For evergreen explainers, the best piece wins regardless of date. One ranking model can't serve both, and most media search picks one and fails the other.
03
In media, entities carry the meaning.
People, organizations, places, events, and ongoing stories. Readers search "that senator from the hearing" more often than they search a headline phrase.
04
Media content types are genuinely different.
Articles, video, podcasts, photo galleries, interactives, newsletters. A reader searching a topic wants the best coverage, not the best article — which means multiple formats need to compete in one result set.
05
Rights and access are constraints.
Syndicated material, licensed imagery, territorial restrictions, and paywalls all determine what a given reader can actually be shown.
06
Media publication velocity is high.
Breaking news must be searchable within minutes, not on tonight's index rebuild.
How AI is changing media content search
Semantic retrieval over the archive.
Semantic search for media websites matches meaning rather than headline wording, which is what lets a half-remembered description find the right piece. This is the single highest-value improvement for publishers, because it's what finally makes the archive retrievable. Our what is semantic search guide covers the mechanics.
Entity extraction and linking.
Recognizing that a story is about a person, organization, or event — and connecting it to every other piece about them. This turns a flat archive into a navigable graph, and it's the foundation of topic pages that actually work.
Blended ranking that respects intent.
Detecting whether a query is news-seeking or reference-seeking, and weighting recency accordingly. "Election results" wants today; "how does ranked choice voting work" doesn't.
Transcript-level indexing for audio and video.
Speech recognition has become accurate and cheap enough that transcribing your entire back catalogue is now routine rather than a project. That makes AI video search practical at the level readers want — not "which video" but "where in the video."
Our query understanding guide covers intent detection, and hybrid search covers pairing semantic retrieval with exact matching — necessary because readers also search precise names, quotes, and headlines that must resolve literally.
The AI crawler question — and why publishers should answer it differently
Which means there's no universal answer, and anyone offering you one is selling something. The considerations that actually matter:
What's your revenue model?
Subscription publishers lose more to full-answer substitution than ad-supported ones lose to reduced pageviews — though both lose something.
Is your content substitutable?
Commodity news gets summarized and replaced easily. Distinctive investigative work, proprietary data, and specialist analysis are harder to substitute and more likely to drive a click through to the source.
Have you licensed, or could you?
Several publishers have negotiated content agreements with AI companies rather than choosing between blocking and giving it away. That option didn't exist two years ago.
Are you differentiating by crawler?
The technical detail matters here: these are separate user agents with separate directives, and blocking one doesn't block the others. Our AI crawlers guide covers the mechanics, and AI visibility covers measurement — read both with this commercial caveat in mind.
AI video search: finding the moment, not the file
Transcription
converts speech to searchable text, including speaker identification where multiple voices matter.
Segmentation
breaks the transcript into coherent passages rather than treating a whole episode as one document. Without this, a semantic match against a forty-minute transcript tells you the topic appears somewhere in it.
Timestamp retrieval
returns the specific moment, with enough surrounding context for the reader to judge relevance .
The same pipeline applies to podcasts, where transcript search is often the only way anything gets found. Publishers with large audio archives frequently discover that transcription alone unlocks more value than any ranking work.
How to improve media content discovery — the measurable version
01
Zero-result rate on archive queries.
Segment archive searches from recent-content searches; they fail for different reasons.
02
Search-to-read-through rate.
Not just clicks — did readers actually engage with what search returned?
03
Archive activation.
What share of your back catalogue received any impressions this quarter? Most publishers who measure this for the first time are startled, and it's the number that quantifies what better search unlocks.
04
Content-type distribution in results.
If video and audio never surface, your media content search is effectively text-only regardless of what's indexed.
05
Session depth from search.
Whether search leads readers deeper or ends the visit. Our search relevance metrics and A/B testing guides cover methodology, and search returned no results covers recovery design.
Rights, paywalls, and access
Paywall-aware results.
Should subscriber-only pieces appear to non-subscribers? Most publishers say yes with clear labeling, since it demonstrates value — but the results page has to signal access honestly rather than producing a click-into-a-wall.
Syndicated content limits.
Wire material and licensed pieces may carry display or territorial restrictions that search must honor.
Image and video licensing.
Rights windows expire. An asset legitimately used in 2022 may not be licensed for use today, which makes rights metadata a first-class search constraint rather than an afterthought.
Takedowns and corrections.
Removed or corrected content must disappear from or update in the index immediately — this is a legal and editorial requirement, not a quality nicety. It's the clearest case in publishing where real-time indexing is a compliance need.
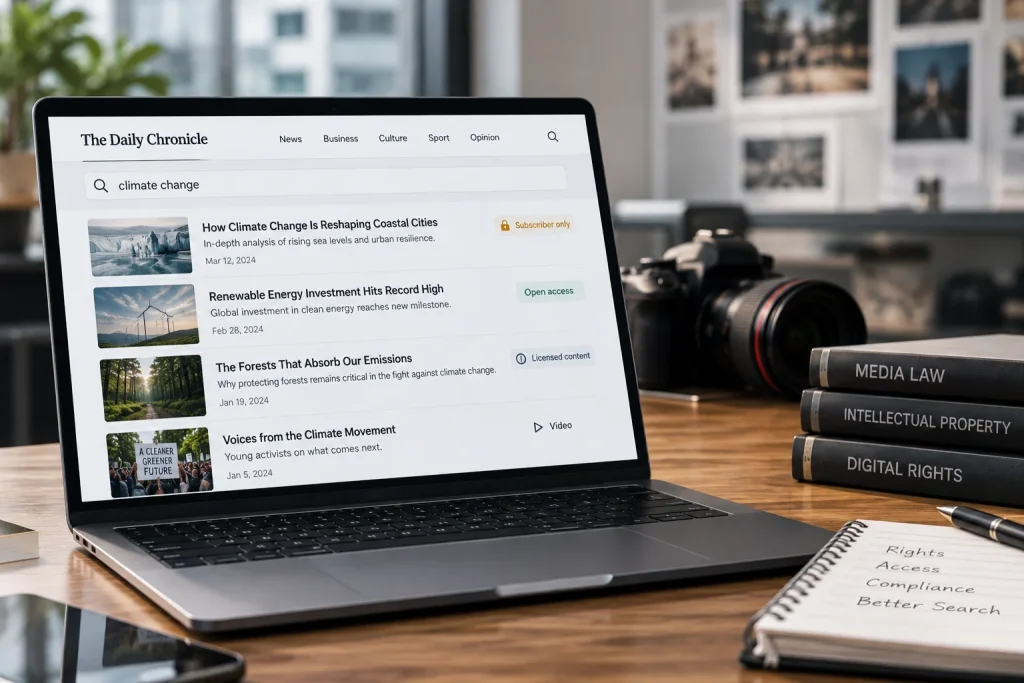
Treating rights as structured, searchable metadata rather than free text in a digital asset management system is what makes automated enforcement possible.
AI content discovery for media companies
Related content that understands topic, not just tags
— the foundation of how AI improves media content discovery. Manual tagging is inconsistent and decays. Semantic similarity finds genuinely related pieces including ones nobody tagged correctly, which is where archive value actually surfaces.
Topic and story pages built automatically.
Entity linking lets you generate coherent pages for an ongoing story, a recurring subject, or a named individual — assembling coverage that would otherwise require manual curation nobody has time for.
Personalized recommendations with editorial guardrails.
Pure behavioral recommendation narrows readers into a rut, which is a genuine editorial problem in news rather than only a commercial one. Reserve a portion of recommendations for editorial priority and deliberate breadth. Our vector database for recommendations guide covers the retrieval architecture.
Archive resurfacing.
Evergreen media pieces tied to recurring events, anniversaries, or newly relevant topics. This is the cheapest content you'll ever publish, because you already published it.
What to require from a platform
Hybrid retrieval
since readers search both descriptions and exact names or quotes.
Rights and access awareness
applied at query time.
Entity extraction and linking
for people, organizations, places, and events.
Recency controls
that can be tuned per query intent rather than applied globally.
Multi-format indexing
covering articles, video transcripts, audio, and image metadata with type as a facet.
Archive-scale performance
— filtered queries across millions of documents without degradation, covered in our AI search for large catalogs guide.
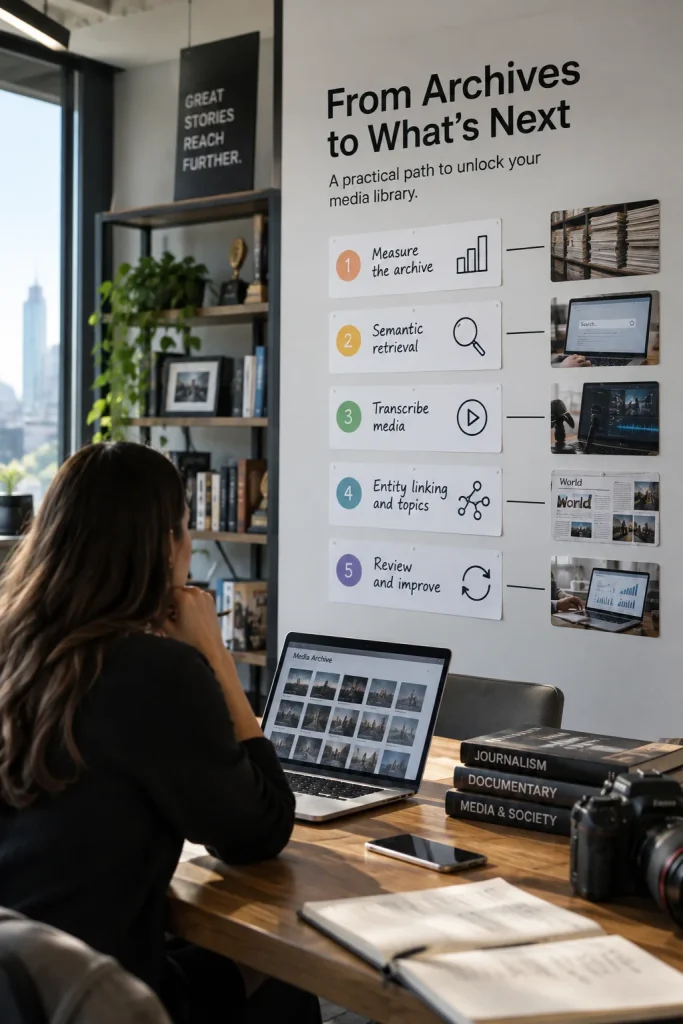
A realistic sequence
Media FAQs
What is AI search for media?
How is AI changing media content search?
What is AI video search and how does it work?
Should media companies block AI crawlers?
How does semantic search for media websites differ from regular site search?
What is AI content discovery for media companies?
How do I measure whether media search is working?